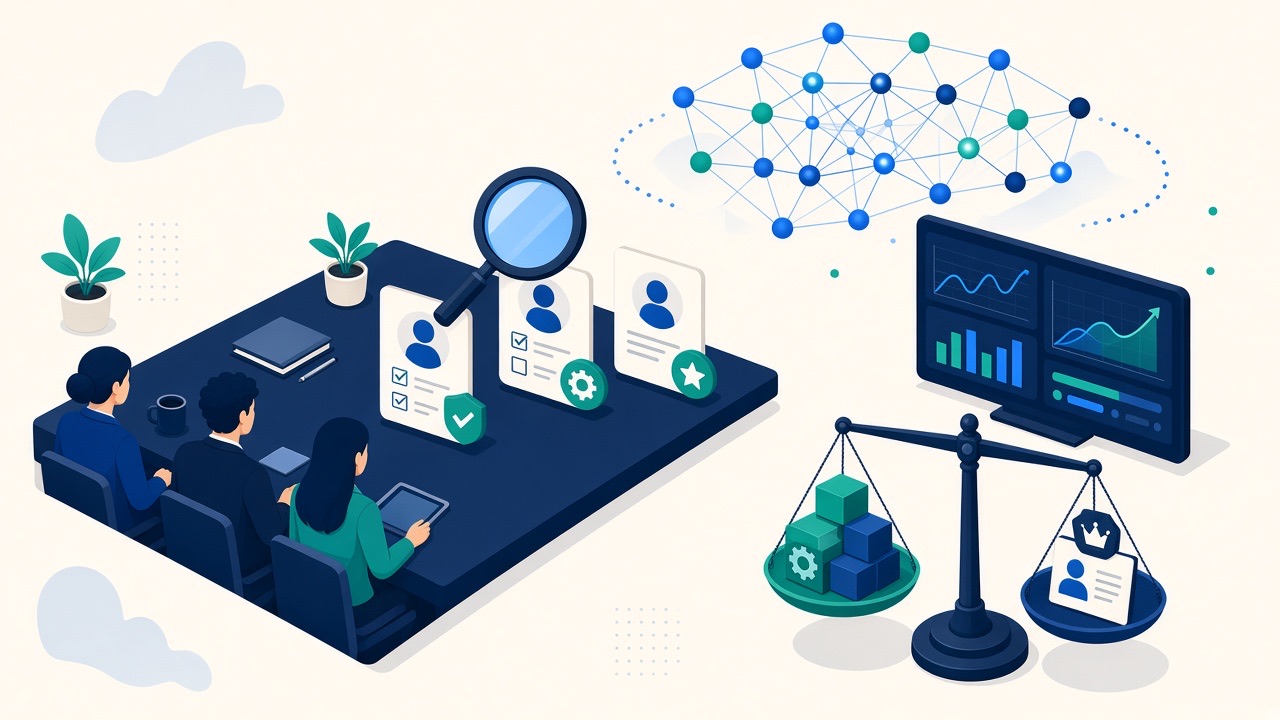
Boards want AI outcomes; engineering leaders need reliability and compliance. Procurement often wants a rate card. Those three pressures collide in hiring briefs that read like buzzword bingo. The result is expensive interviews, mismatched expectations, and pods that look full on paper while throughput stalls.
The business problem: optimising the wrong scorecard
When hiring optimises for title density or generic puzzle performance, you select for interview skill, not the judgement required to ship models under latency budgets, handle drift, or document lineage for auditors. The market also responds to incentives: inflated titles are rational for candidates when job descriptions are vague.
Operational approach: roles as delivery primitives
Start by naming what must be true in production: data freshness contracts, offline versus online evaluation, monitoring hooks, human review gates, and where personally identifiable information may never travel. Each primitive becomes a hiring dimension with explicit interview evidence, not a keyword list.
| Delivery primitive | What “good” looks like in interview |
|---|---|
| Evaluation discipline | Candidate designs a minimal harness for a stated failure mode |
| Latency budget | Trade-offs between batch and online scoring explained clearly |
| Governance | Logging, access boundaries, and rollback described before model math |
Commercial structure that preserves quality
Seat-only pricing hides variance inside a rate band. Milestone-based pods with explicit risk ownership align incentives: partners are rewarded for outcomes and transparency, not for filling seats quickly. This does not mean adversarial contracting. It means clarity about what “done” means for each release slice.
- ShippingInterview focusscoped exercise in client domain
- Title inflationAvoidwithout primitive mapping
- MilestonesContract anchorplus explicit risk ownership
Enterprise takeaways
Rewrite one pilot requisition with primitives, run a shadow loop with your strongest engineers scoring evidence, not speed, and compare offer acceptance and early performance at ninety days. Iterate the brief before you scale hiring. The market will still be competitive; your edge is coherence.
Interview loops that predict delivery
Strong AI hiring loops look less like exams and more like the work. Replace abstract puzzle rounds with a structured conversation about a model the candidate has shipped: how the data was gathered and cleaned, how evaluation was set up, what broke in production, and what they would do differently. Engineers who have operated real systems answer these questions concretely; those who have only experimented tend to stay general.
Add a short practical exercise grounded in your domain, such as reviewing a flawed evaluation setup or diagnosing drift from a few charts, rather than a take-home that consumes a weekend. Score against a written rubric agreed before interviews start, so that panels in different time zones reach consistent decisions.
Building the team in the right order
Many AI teams hire research-leaning profiles first and discover later that nobody owns data pipelines, feature stores, or deployment. A more reliable sequence starts with a data engineer and an ML engineer who can put a simple model into production, then adds specialists as the use cases prove themselves.
Keep product and domain ownership close to the team. AI work that is disconnected from the people who understand the customer problem tends to optimise metrics that do not matter. Pair each AI squad with a product owner who can say clearly what “better” means for the business.
Closing
AI hiring in India is not a volume problem. It is a specification problem. Treat hiring briefs like architecture specs: precise, testable, and aligned to production reality. That is how you avoid paying a premium for the wrong skills while missing the engineers who will actually carry your roadmap.
Working through this in your own GCC plan?
We will give a direct answer on a short call.